


Life is always full of ups and downs. No one will always live a peaceful life. Maybe you have been at the bottom of your life; but it's difficult for you to cheer up. I am glad to tell you that our Associate-Developer-Apache-Spark-3.5 study guide: Databricks Certified Associate Developer for Apache Spark 3.5 - Python will give you a chance to start again. As old saying goes, failure is mother to success as it can strengthen one's will. If you are determined to succeed, our Associate-Developer-Apache-Spark-3.5 learning materials will be sure to give you a hand. After you have tried our Associate-Developer-Apache-Spark-3.5 test dumps materials, you must be satisfied with our products.

Free demo before you decide to buy our Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam study materials
Maybe you are the first time to buy our test questions and you feel uncertain about our Databricks Associate-Developer-Apache-Spark-3.5 exam preparatory. It doesn't matter, we offer you free demo to have a try before you decide to buy our Associate-Developer-Apache-Spark-3.5 exam questions: Databricks Certified Associate Developer for Apache Spark 3.5 - Python. The free demo supports to download online. If you want to check the ability of our test questions, please download the free demo on our website. After you have experienced our free demo of Associate-Developer-Apache-Spark-3.5 exam questions, you will fully trust us. What you need to pay attention to is that the free demo does not include the whole knowledge of the Associate-Developer-Apache-Spark-3.5 certification training: Databricks Certified Associate Developer for Apache Spark 3.5 - Python. If you are satisfied with our free demo, please buy our Associate-Developer-Apache-Spark-3.5 practice test materials. Our company has always provided the best products to our customers.
Three versions of Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam study materials
When a product can meet different kinds of demands of customers, it must be a successful product. Our Associate-Developer-Apache-Spark-3.5 study guide: Databricks Certified Associate Developer for Apache Spark 3.5 - Python totally have such great advantages. Our specialists have triumphantly developed the three versions of the Associate-Developer-Apache-Spark-3.5 learning materials. They are the app version, software and the pdf version. Each version is aimed at satisfying different customers' demand. At the same time, the three versions can be combined together, which will bring the greatest learning results. The three versions of our Associate-Developer-Apache-Spark-3.5 exam preparatory files have respective advantage. For example, the app version can be installed on your mobile phone, which is easy for you to learn when you go out. The windows software can give you the real experience of the Databricks Associate-Developer-Apache-Spark-3.5 exam. The pdf version is convenient for you to make notes. All in all, the three versions can help you pass the Databricks Associate-Developer-Apache-Spark-3.5 exam and gain the certificate.
The advantages of passing the Databricks Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam
Passing the Databricks Associate-Developer-Apache-Spark-3.5 exam is very important for you to choose a good job. Once you have passed the exam, you will have many choices. First of all, many large corporations urgently need such talent, which means you will have a better chance to be employed among many other candidates (Associate-Developer-Apache-Spark-3.5 learning materials). Secondly, passing the exam means you have grasped a very useful skill and learn much knowledge. You are easily to be thought highly by your boss, which means you will easily get promotion than your colleagues. In a word, there are many other benefits if you pass the exam. Come and choose our Associate-Developer-Apache-Spark-3.5 study guide: Databricks Certified Associate Developer for Apache Spark 3.5 - Python.
Instant Download Associate-Developer-Apache-Spark-3.5 Exam Braindumps: Upon successful payment, Our systems will automatically send the product you have purchased to your mailbox by email. (If not received within 12 hours, please contact us. Note: don't forget to check your spam.)
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Using Spark Connect to Deploy Applications | 5% | - Running applications via Spark Connect - Connecting to remote Spark clusters - Spark Connect architecture |
| Topic 2: Using Pandas API on Apache Spark | 5% | - Key differences and limitations - Converting between Pandas and Spark structures - Overview of Pandas API on Spark |
| Topic 3: Troubleshooting and Tuning Apache Spark DataFrame API Applications | 10% | - Optimizing transformations and actions - Identifying performance bottlenecks - Managing memory and resource usage - Debugging and logging |
| Topic 4: Developing Apache Spark DataFrame API Applications | 30% | - User-defined functions (UDFs) - Handling missing values and data quality - Filtering, sorting, and aggregating data - Reading and writing data in various formats - Partitioning and bucketing data - Selecting, renaming, and modifying columns - Joining and combining datasets - Creating DataFrames and defining schemas |
| Topic 5: Using Spark SQL | 20% | - Working with functions and expressions - Integrating Spark SQL with DataFrames - Using catalog and metadata APIs - Running SQL queries |
| Topic 6: Structured Streaming | 10% | - Fault tolerance and state management - Output modes and triggers - Defining streaming queries - Streaming concepts and architecture |
| Topic 7: Apache Spark Architecture and Components | 20% | - Execution hierarchy and lazy evaluation - Shuffling, actions, and broadcasting - Execution and deployment modes - Spark architecture overview - Fault tolerance and garbage collection |
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
12 of 55.
A data scientist has been investigating user profile data to build features for their model. After some exploratory data analysis, the data scientist identified that some records in the user profiles contain NULL values in too many fields to be useful.
The schema of the user profile table looks like this:
user_id STRING,
username STRING,
date_of_birth DATE,
country STRING,
created_at TIMESTAMP
The data scientist decided that if any record contains a NULL value in any field, they want to remove that record from the output before further processing.
Which block of Spark code can be used to achieve these requirements?
- A. filtered_users = raw_users.dropna(how="all")
- B. filtered_users = raw_users.na.drop("any")
- C. filtered_users = raw_users.na.drop("all")
- D. filtered_users = raw_users.dropna(how="any")
Correct Answer: D 🗳️
Explanation: Only visible for DumpsTorrent members. You can sign-up / login (it's free).
Given the code fragment: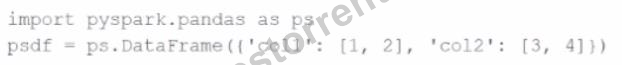
import pyspark.pandas as ps
psdf = ps.DataFrame({'col1': [1, 2], 'col2': [3, 4]})
Which method is used to convert a Pandas API on Spark DataFrame (pyspark.pandas.DataFrame) into a standard PySpark DataFrame (pyspark.sql.DataFrame)?
- A. psdf.to_pandas()
- B. psdf.to_spark()
- C. psdf.to_dataframe()
- D. psdf.to_pyspark()
Correct Answer: B 🗳️
Explanation: Only visible for DumpsTorrent members. You can sign-up / login (it's free).
22 of 55.
A Spark application needs to read multiple Parquet files from a directory where the files have differing but compatible schemas.
The data engineer wants to create a DataFrame that includes all columns from all files.
Which code should the data engineer use to read the Parquet files and include all columns using Apache Spark?
- A. spark.read.option("mergeSchema", True).parquet("/data/parquet/")
- B. spark.read.parquet("/data/parquet/")
- C. spark.read.format("parquet").option("inferSchema", "true").load("/data/parquet/")
- D. spark.read.parquet("/data/parquet/").option("mergeAllCols", True)
Correct Answer: A 🗳️
Explanation: Only visible for DumpsTorrent members. You can sign-up / login (it's free).
A data scientist is working on a large dataset in Apache Spark using PySpark. The data scientist has a DataFrame df with columns user_id, product_id, and purchase_amount and needs to perform some operations on this data efficiently.
Which sequence of operations results in transformations that require a shuffle followed by transformations that do not?
- A. df.withColumn("purchase_date", current_date()).where("total_purchase > 50")
- B. df.filter(df.purchase_amount > 100).groupBy("user_id").sum("purchase_amount")
- C. df.withColumn("discount", df.purchase_amount * 0.1).select("discount")
- D. df.groupBy("user_id").agg(sum("purchase_amount").alias("total_purchase")).repartition(10)
Correct Answer: D 🗳️
Explanation: Only visible for DumpsTorrent members. You can sign-up / login (it's free).
Given a DataFrame df that has 10 partitions, after running the code:
result = df.coalesce(20)
How many partitions will the result DataFrame have?
- A. 10
- B. 20
- C. Same number as the cluster executors
- D. 1
Correct Answer: A 🗳️
Explanation: Only visible for DumpsTorrent members. You can sign-up / login (it's free).

 Louis

 Dolores

 Debby
 Breenda
 Ford
 Olivia
 Arthur
 Tobias

 Rock
 Malcolm
 Lionel
 Pag
 Earl
 Christopher


